Try it out
Elastic Cloud Serverless projects are autoscaled environments, fully managed by Elastic and available on Elastic Cloud. Availability This functionality is generally available and ready for production usage. Serverless interfaces and procedures might differ from classic Elastic Stack deployments. The Elastic Stack includes Elastic's core products such as Elasticsearch, Kibana, Logstash, and Beats. Availability This functionality is generally available and ready for production usage. Unless stated otherwise on the page, this functionality is available when your Elastic Stack is deployed on Elastic Cloud Hosted, Elastic Cloud Enterprise, Elastic Cloud on Kubernetes, and self-managed environments. This documentation corresponds to the latest patch available for each minor version. If you're not using the latest patch, check the release notes for changes.
Serverless
Generally available
Stack
Generally available
When the model is deployed on at least one node in the cluster, you can begin to perform inference. Inference is a machine learning feature that enables you to use your trained models to perform NLP tasks (such as text extraction, classification, or embeddings) on incoming data.
The simplest method to test your model against new data is to use the Test model action in Kibana. You can either provide some input text or use a field of an existing index in your cluster to test the model:
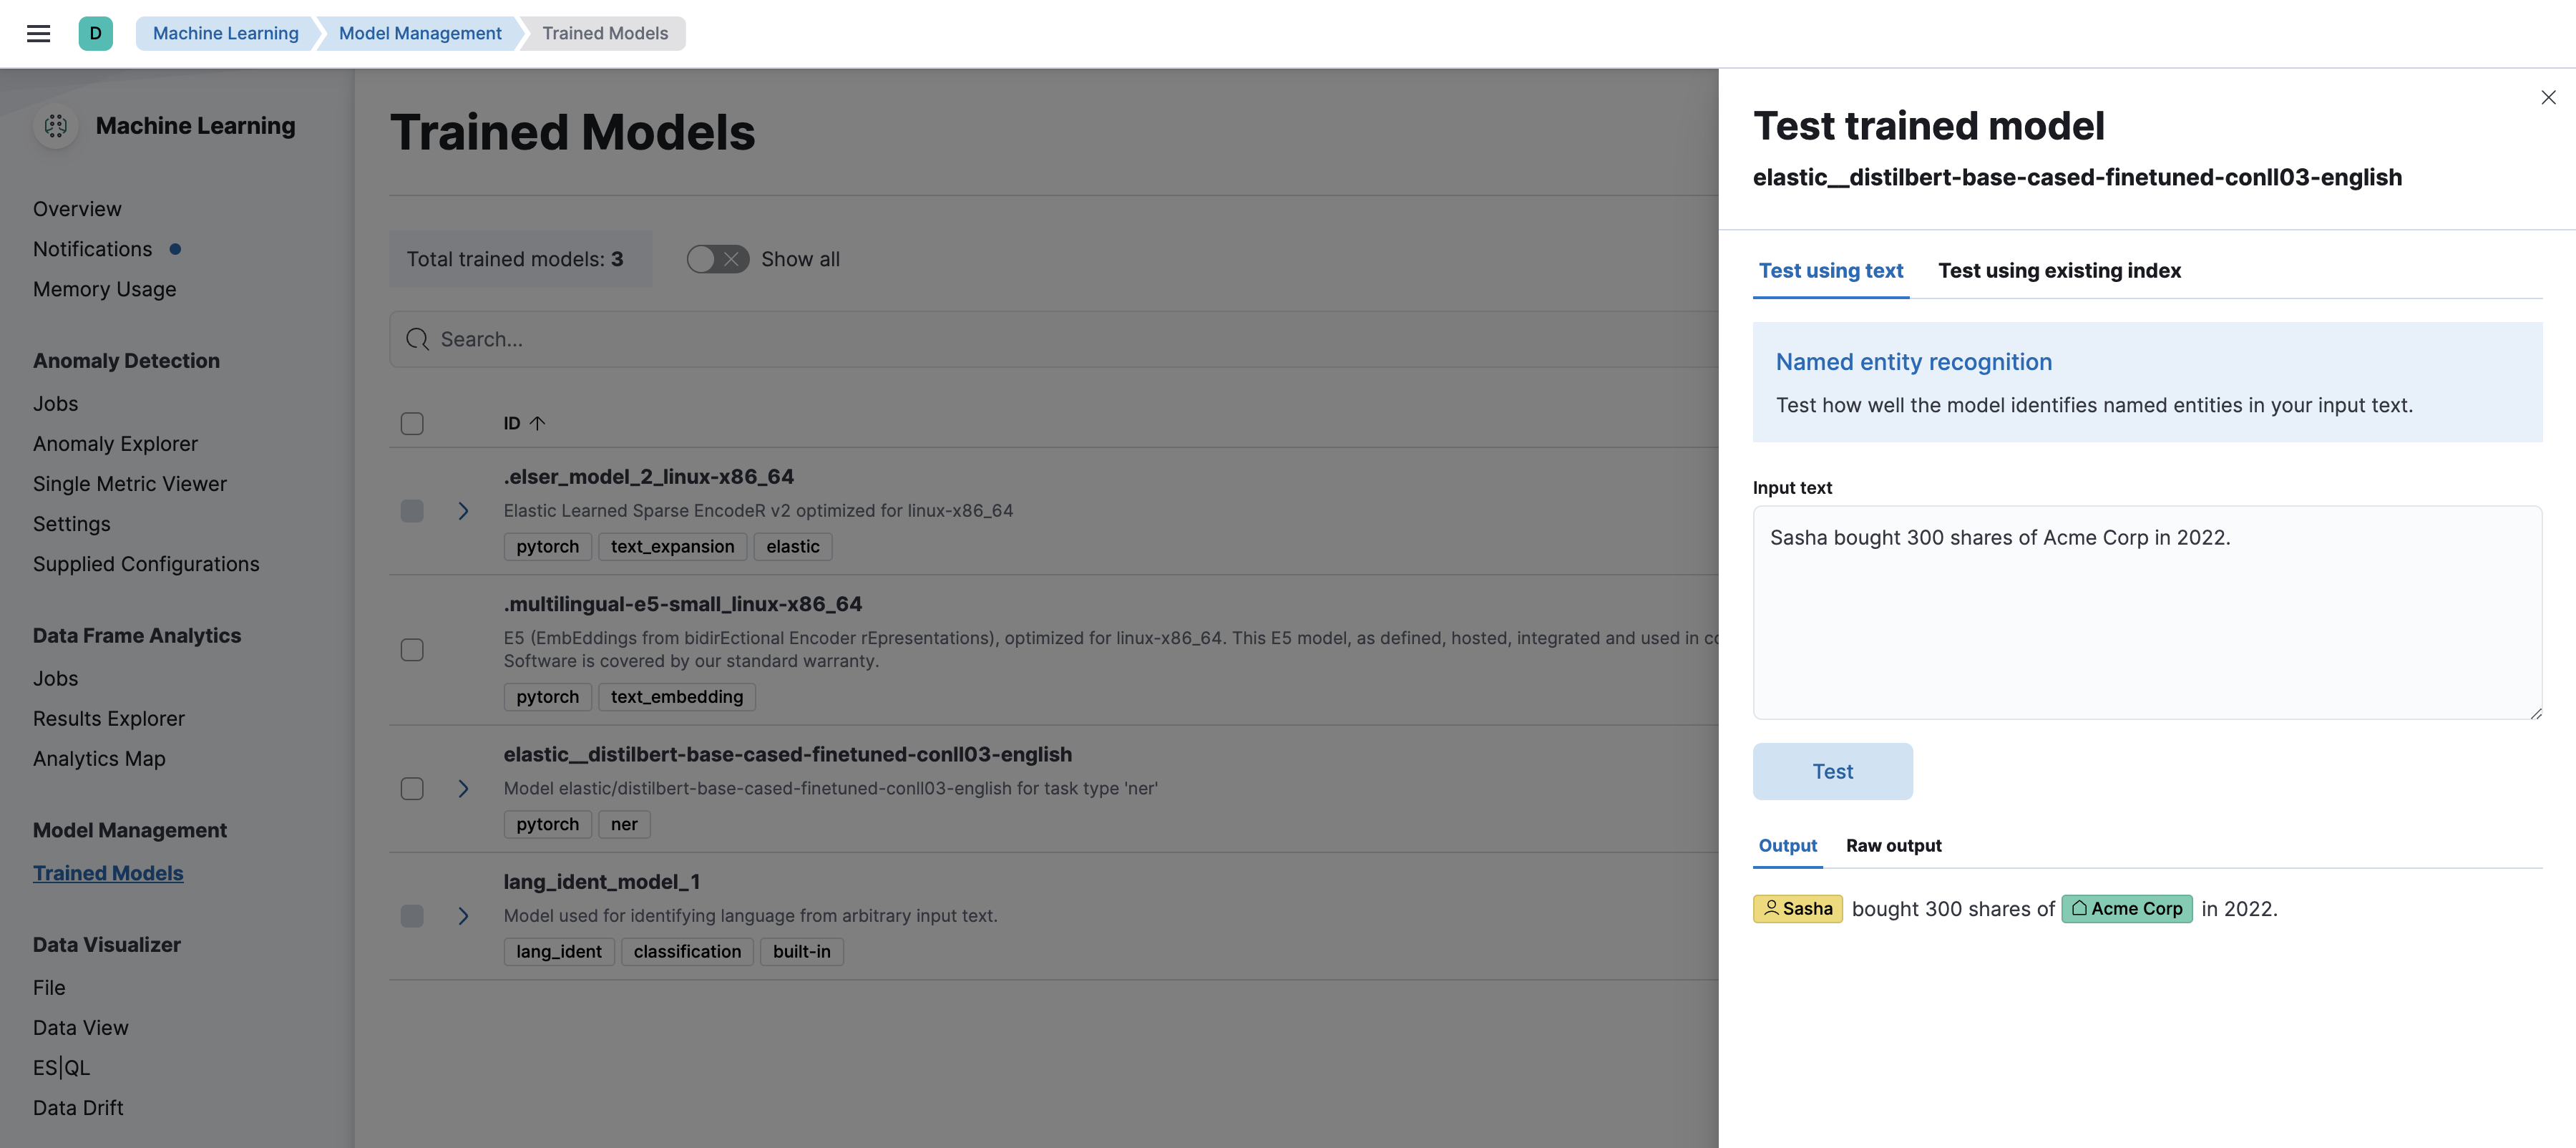
Alternatively, you can use the infer trained model API. For example, to try a named entity recognition task, provide some sample text:
POST /_ml/trained_models/elastic__distilbert-base-cased-finetuned-conll03-english/_infer{ "docs":[{"text_field": "Sasha bought 300 shares of Acme Corp in 2022."}] }
In this example, the response contains the annotated text output and the recognized entities:
{
  "inference_results" : [
    {
      "predicted_value" : "[Sasha](PER&Sasha) bought 300 shares of [Acme Corp](ORG&Acme+Corp) in 2022.",
      "entities" : [
        {
          "entity" : "Sasha",
          "class_name" : "PER",
          "class_probability" : 0.9953193407987492,
          "start_pos" : 0,
          "end_pos" : 5
        },
        {
          "entity" : "Acme Corp",
          "class_name" : "ORG",
          "class_probability" : 0.9996392198381716,
          "start_pos" : 27,
          "end_pos" : 36
        }
      ]
    }
  ]
}
If you are satisfied with the results, you can add these NLP tasks in your ingestion pipelines.