ES|QL CHUNK function
Elastic Cloud Serverless projects are autoscaled environments, fully managed by Elastic and available on Elastic Cloud. Availability This functionality is in technical preview and is ready for evaluation. Use with caution in production; it is not recommended for mission-critical workloads. Elastic will work to fix any issues, but features in technical preview are not subject to the support SLA of official GA features. Specific Support terms apply. Serverless interfaces and procedures might differ from classic Elastic Stack deployments. The Elastic Stack includes Elastic's core products such as Elasticsearch, Kibana, Logstash, and Beats. Availability This functionality is in technical preview and is ready for evaluation. Use with caution in production; it is not recommended for mission-critical workloads. Elastic will work to fix any issues, but features in technical preview are not subject to the support SLA of official GA features. Specific Support terms apply. Unless stated otherwise on the page, this functionality is available when your Elastic Stack is deployed on Elastic Cloud Hosted, Elastic Cloud Enterprise, Elastic Cloud on Kubernetes, and self-managed environments. This documentation corresponds to the latest patch available for each minor version. If you're not using the latest patch, check the release notes for changes.
Serverless
Preview
Preview
Stack
Preview
9.3+
Preview since 9.3
Splits a text field into smaller chunks.
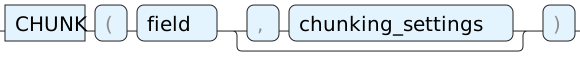
field- The input to chunk. The input can be a single-valued or multi-valued field. In the case of a multi-valued argument, each value is chunked separately.
chunking_settings-
Options to customize chunking behavior. Defaults to {"strategy":"sentence","max_chunk_size":300,"sentence_overlap":0}.
Use CHUNK to split a text field into smaller chunks.
Chunk can be used on fields from the text family like text and semantic_text.
Chunk will split a text field into smaller chunks. By default it uses a sentence-based chunking strategy;
the strategy and its parameters are configurable via the chunking_settings parameter.
The number of chunks returned, and the length of the sentences used to create the chunks can be specified.
| field | chunking_settings | result |
|---|---|---|
| keyword | named parameters | keyword |
| keyword | keyword | |
| text | named parameters | keyword |
| text | keyword |
strategy- (keyword) The chunking strategy to use. Default value is
sentence. Available strategies:
sentence: splits at sentence boundaries. Usesentence_overlapto share a sentence between adjacent chunks.word: splits on individual words. Useoverlapto share words between adjacent chunks.recursive: splits using configurable separator patterns — either a predefinedseparator_group(plaintextormarkdown) or a custom list ofseparators— falling back to sentence-level splitting when no separator produces a chunk withinmax_chunk_size.none: returns the entire input as a single chunk.
For a full description of each strategy and how its options interact, refer to chunking strategies.
max_chunk_size- (integer) The maximum size of a chunk in words. This value cannot be lower than
20(forsentencestrategy) or10(forwordorrecursivestrategies). This model should not exceed the window size for any associated models using the output of this function. overlap- (integer) The number of overlapping words for chunks. It is applicable only to a
wordchunking strategy. This value cannot be higher than half themax_chunk_sizevalue. sentence_overlap- (integer) The number of overlapping sentences for chunks. It is applicable only for a
sentencechunking strategy. It can be either1or0. Defaults to0. separator_group- (keyword) Sets a predefined lists of separators based on the selected text type. Values may be
markdownorplaintext. Only applicable to therecursivechunking strategy. When using therecursivechunking strategy one ofseparatorsorseparator_groupmust be specified. separators-
(keyword) A list of strings used as possible split points when chunking text. Each string can be a plain string or a regular expression (regex) pattern. The system tries each separator in order to split the text, starting from the first item in the list. After splitting, it attempts to recombine smaller pieces into larger chunks that stay within the
max_chunk_sizelimit, to reduce the total number of chunks generated. Only applicable to therecursivechunking strategy. When using therecursivechunking strategy one ofseparatorsorseparator_groupmust be specified.
The Elastic Stack includes Elastic's core products such as Elasticsearch, Kibana, Logstash, and Beats. Availability This functionality is in technical preview and is ready for evaluation. Use with caution in production; it is not recommended for mission-critical workloads. Elastic will work to fix any issues, but features in technical preview are not subject to the support SLA of official GA features. Specific Support terms apply. Unless stated otherwise on the page, this functionality is available when your Elastic Stack is deployed on Elastic Cloud Hosted, Elastic Cloud Enterprise, Elastic Cloud on Kubernetes, and self-managed environments. This documentation corresponds to the latest patch available for each minor version. If you're not using the latest patch, check the release notes for changes.
Stack
Preview
9.3+
Preview since 9.3
ROW result = CHUNK("It was the best of times, it was the worst of times, it was the age of wisdom, it was the age of foolishness, it was the epoch of belief.", {"strategy": "word", "max_chunk_size": 10, "overlap": 1})
| MV_EXPAND result
| result:keyword |
|---|
| It was the best of times, it was the worst |
| worst of times, it was the age of wisdom, it |
| , it was the age of foolishness, it was the epoch |
| epoch of belief. |