ES|QL MATCH function
Elastic Cloud Serverless projects are autoscaled environments, fully managed by Elastic and available on Elastic Cloud. Availability This functionality is generally available and ready for production usage. Serverless interfaces and procedures might differ from classic Elastic Stack deployments. The Elastic Stack includes Elastic's core products such as Elasticsearch, Kibana, Logstash, and Beats. Availability This functionality is generally available and ready for production usage. This functionality is in technical preview and is ready for evaluation. Use with caution in production; it is not recommended for mission-critical workloads. Elastic will work to fix any issues, but features in technical preview are not subject to the support SLA of official GA features. Specific Support terms apply. Unless stated otherwise on the page, this functionality is available when your Elastic Stack is deployed on Elastic Cloud Hosted, Elastic Cloud Enterprise, Elastic Cloud on Kubernetes, and self-managed environments. This documentation corresponds to the latest patch available for each minor version. If you're not using the latest patch, check the release notes for changes.
Serverless
Generally available
Stack
GA
9.1+
…
Generally available since 9.1
Preview in 9.0
Performs a match query on the specified field or expression.
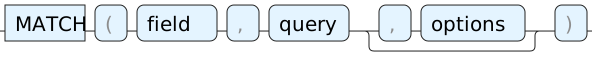
field- Field or expression that the query will target.
query- Value to find in the provided field or expression.
options-
(Optional) Match additional options as function named parameters.
Use MATCH to perform a match query on the specified field or expression. Using MATCH is equivalent to using the match query in the Elasticsearch Query DSL.
Match can be used on fields from the text family like text and semantic_text, as well as other field types like keyword, boolean, dates, and numeric types. When Match is used on a semantic_text field, it will perform a semantic query on the field.
Match can use function named parameters to specify additional options for the match query. All match query parameters are supported.
For a simplified syntax, you can use the match operator : operator instead of MATCH.
MATCH returns true if the provided query matches the row.
MATCH on expressions
The Elastic Stack includes Elastic's core products such as Elasticsearch, Kibana, Logstash, and Beats.
Availability
Preview in 9.5
This functionality is in technical preview and is ready for evaluation. Use with caution in production; it is not recommended for mission-critical workloads. Elastic will work to fix any issues, but features in technical preview are not subject to the support SLA of official GA features. Specific Support terms apply.
Unless stated otherwise on the page, this functionality is available when your Elastic Stack is deployed on Elastic Cloud Hosted, Elastic Cloud Enterprise, Elastic Cloud on Kubernetes, and self-managed environments.
This documentation corresponds to the latest patch available for each minor version. If you're not using the latest patch, check the release notes for changes.
Elastic Cloud Serverless projects are autoscaled environments, fully managed by Elastic and available on Elastic Cloud.
Availability
Generally available
This functionality is generally available and ready for production usage.
Serverless interfaces and procedures might differ from classic Elastic Stack deployments.
MATCH can also search expressions that are not backed by an index, such as
computed columns produced by EVAL, STATS, or other commands.
When the target is not an indexed field, the search evaluates by scanning
values row by row, which may be slower on large datasets.
Analyzers, options, and scoring work differently than on an indexed field.
To learn more, refer to runtime search.
Learn more about using ES|QL for search use cases.
| field | query | options | result |
|---|---|---|---|
| boolean | boolean | named parameters | boolean |
| boolean | keyword | named parameters | boolean |
| date | date | named parameters | boolean |
| date | keyword | named parameters | boolean |
| date_nanos | date_nanos | named parameters | boolean |
| date_nanos | keyword | named parameters | boolean |
| double | double | named parameters | boolean |
| double | integer | named parameters | boolean |
| double | keyword | named parameters | boolean |
| double | long | named parameters | boolean |
| integer | double | named parameters | boolean |
| integer | integer | named parameters | boolean |
| integer | keyword | named parameters | boolean |
| integer | long | named parameters | boolean |
| ip | ip | named parameters | boolean |
| ip | keyword | named parameters | boolean |
| keyword | keyword | named parameters | boolean |
| long | double | named parameters | boolean |
| long | integer | named parameters | boolean |
| long | keyword | named parameters | boolean |
| long | long | named parameters | boolean |
| text | keyword | named parameters | boolean |
| unsigned_long | double | named parameters | boolean |
| unsigned_long | integer | named parameters | boolean |
| unsigned_long | keyword | named parameters | boolean |
| unsigned_long | long | named parameters | boolean |
| unsigned_long | unsigned_long | named parameters | boolean |
| version | keyword | named parameters | boolean |
| version | version | named parameters | boolean |
analyzer- (keyword) Analyzer used to convert the text in the query value into tokens. Defaults to the index-time analyzer mapped for the field. If no analyzer is mapped, the index’s default analyzer is used. For expressions not backed by an index, defaults to the values analyzer declared through
TO_TEXT(standardwhen none is declared). auto_generate_synonyms_phrase_query- (boolean) If true, match phrase queries are automatically created for multi-term synonyms. Defaults to true.
fuzziness- (keyword) Maximum edit distance allowed for matching.
boost- (float) Floating point number used to decrease or increase the relevance scores of the query. Defaults to 1.0.
fuzzy_transpositions- (boolean) If true, edits for fuzzy matching include transpositions of two adjacent characters (ab → ba). Defaults to true.
fuzzy_rewrite- (keyword) Method used to rewrite the query. See the rewrite parameter for valid values and more information. If the fuzziness parameter is not 0, the match query uses a fuzzy_rewrite method of top_terms_blended_freqs_${max_expansions} by default.
lenient- (boolean) If false, format-based errors, such as a text query value for a numeric field, are returned. If true, such values do not match. Defaults to true.
max_expansions- (integer) Maximum number of terms to which the query will expand. Defaults to 50.
minimum_should_match- (integer) Minimum number of clauses that must match for a document to be returned.
operator- (keyword) Boolean logic used to interpret text in the query value. Defaults to OR.
prefix_length- (integer) Number of beginning characters left unchanged for fuzzy matching. Defaults to 0.
zero_terms_query-
(keyword) Indicates whether all documents or none are returned if the analyzer removes all tokens, such as when using a stop filter. Defaults to none.
FROM books
| WHERE MATCH(author, "Faulkner")
| book_no:keyword | author:text |
|---|---|
| 2378 | [Carol Faulkner, Holly Byers Ochoa, Lucretia Mott] |
| 2713 | William Faulkner |
| 2847 | Colleen Faulkner |
| 2883 | William Faulkner |
| 3293 | Danny Faulkner |
FROM books
| WHERE MATCH(title, "Hobbit Back Again", {"operator": "AND"})
| KEEP title;
| title:text |
|---|
| The Hobbit or There and Back Again |