ES|QL CATEGORIZE function
The CATEGORIZE function requires a platinum license.
Elastic Cloud Serverless projects are autoscaled environments, fully managed by Elastic and available on Elastic Cloud. Availability This functionality is generally available and ready for production usage. Serverless interfaces and procedures might differ from classic Elastic Stack deployments. The Elastic Stack includes Elastic's core products such as Elasticsearch, Kibana, Logstash, and Beats. Availability This functionality is generally available and ready for production usage. This functionality is in technical preview and is ready for evaluation. Use with caution in production; it is not recommended for mission-critical workloads. Elastic will work to fix any issues, but features in technical preview are not subject to the support SLA of official GA features. Specific Support terms apply. Unless stated otherwise on the page, this functionality is available when your Elastic Stack is deployed on Elastic Cloud Hosted, Elastic Cloud Enterprise, Elastic Cloud on Kubernetes, and self-managed environments. This documentation corresponds to the latest patch available for each minor version. If you're not using the latest patch, check the release notes for changes.
Serverless
Generally available
Stack
GA
9.1+
…
Generally available since 9.1
Preview in 9.0
Groups text messages into categories of similarly formatted text values.
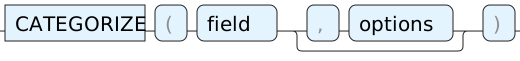
field- Expression to categorize
options-
(Optional) Categorize additional options as function named parameters. The Elastic Stack includes Elastic's core products such as Elasticsearch, Kibana, Logstash, and Beats. Availability Generally available since 9.2 This functionality is generally available and ready for production usage. Unless stated otherwise on the page, this functionality is available when your Elastic Stack is deployed on Elastic Cloud Hosted, Elastic Cloud Enterprise, Elastic Cloud on Kubernetes, and self-managed environments. This documentation corresponds to the latest patch available for each minor version. If you're not using the latest patch, check the release notes for changes. }
Groups text messages into categories of similarly formatted text values.
CATEGORIZE has the following limitations:
- can’t be used within other expressions
- can’t be used more than once in the groupings
- can’t be used or referenced within aggregate functions and it has to be the first grouping
| field | options | result |
|---|---|---|
| keyword | keyword | |
| text | keyword |
analyzer- (keyword) Analyzer used to convert the field into tokens for text categorization.
output_format- (keyword) The output format of the categories. Supported formats are
regex, which outputs a regular expression matching the category, andtokens, which outputs a more human-readable space-separated list of the matching tokens of the category. Defaults toregex. similarity_threshold-
(integer) The minimum percentage of token weight that must match for text to be added to the category bucket. Must be between 1 and 100. The larger the value the narrower the categories. Larger values will increase memory usage and create narrower categories. Defaults to 70.
This example categorizes server logs messages into categories and aggregates their counts.
FROM sample_data
| STATS count=COUNT() BY category=CATEGORIZE(message)
| count:long | category:keyword |
|---|---|
| 3 | .*?Connected.+?to.*? |
| 3 | .*?Connection.+?error.*? |
| 1 | .*?Disconnected.*? |
Group log message categories by time interval by combining CATEGORIZE with BUCKET in the same BY clause.
FROM sample_data
| STATS count = COUNT(*) BY category = CATEGORIZE(message), time_bucket = BUCKET(@timestamp, 1 HOUR)
| SORT time_bucket DESC, count DESC, category
| count:long | category:keyword | time_bucket:datetime |
|---|---|---|
| 3 | .*?Connection.+?error.*? | 2023-10-23T13:00:00.000Z |
| 1 | .*?Connected.+?to.*? | 2023-10-23T13:00:00.000Z |
| 1 | .*?Disconnected.*? | 2023-10-23T13:00:00.000Z |
| 2 | .*?Connected.+?to.*? | 2023-10-23T12:00:00.000Z |
Surface one representative raw message per category by combining CATEGORIZE with SAMPLE.
FROM sample_data
| STATS sample_message = SAMPLE(message, 1) BY category = CATEGORIZE(message)
| SORT category
| sample_message:keyword | category:keyword |
|---|---|
| Connected to 10.1.0.1 | .*?Connected.+?to.*? |
| Connection error | .*?Connection.+?error.*? |
| Disconnected | .*?Disconnected.*? |