ES|QL KNN function
Elastic Cloud Serverless projects are autoscaled environments, fully managed by Elastic and available on Elastic Cloud. Availability This functionality is generally available and ready for production usage. Serverless interfaces and procedures might differ from classic Elastic Stack deployments. The Elastic Stack includes Elastic's core products such as Elasticsearch, Kibana, Logstash, and Beats. Availability This functionality is generally available and ready for production usage. This functionality is in technical preview and is ready for evaluation. Use with caution in production; it is not recommended for mission-critical workloads. Elastic will work to fix any issues, but features in technical preview are not subject to the support SLA of official GA features. Specific Support terms apply. Unless stated otherwise on the page, this functionality is available when your Elastic Stack is deployed on Elastic Cloud Hosted, Elastic Cloud Enterprise, Elastic Cloud on Kubernetes, and self-managed environments. This documentation corresponds to the latest patch available for each minor version. If you're not using the latest patch, check the release notes for changes.
Serverless
Generally available
Stack
GA
9.4+
…
Generally available since 9.4
Preview from 9.2 to 9.3
Finds the k nearest vectors to a query vector as measured by a similarity metric.
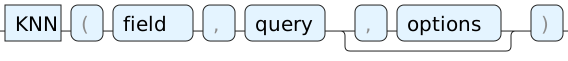
field- Field that the query will target. knn function can be used with dense_vector or semantic_text fields. Other text fields are not allowed
query- Vector value to find top nearest neighbours for.
options-
(Optional) kNN additional options as function named parameters. See knn query for more information.
Finds the k nearest vectors to a query vector, as measured by a similarity metric. knn function finds nearest vectors through approximate search on indexed dense_vectors or semantic_text fields.
The KNN function performs approximate kNN search
on indexed dense_vector and semantic_text fields. It delegates search to the underlying vector search index,
such as disk_bbq.
Elastic Cloud Serverless projects are autoscaled environments, fully managed by Elastic and available on Elastic Cloud. Availability This functionality is in technical preview and is ready for evaluation. Use with caution in production; it is not recommended for mission-critical workloads. Elastic will work to fix any issues, but features in technical preview are not subject to the support SLA of official GA features. Specific Support terms apply. Serverless interfaces and procedures might differ from classic Elastic Stack deployments. The Elastic Stack includes Elastic's core products such as Elasticsearch, Kibana, Logstash, and Beats. Availability We plan to add this functionality in a future Elastic Stack update. Subject to changes. Unless stated otherwise on the page, this functionality is available when your Elastic Stack is deployed on Elastic Cloud Hosted, Elastic Cloud Enterprise, Elastic Cloud on Kubernetes, and self-managed environments. This documentation corresponds to the latest patch available for each minor version. If you're not using the latest patch, check the release notes for changes.
Serverless
Preview
Preview
Stack
Planned
Planned
KNN also works on dense_vector expressions that aren't backed by an index, such as vectors generated by the
DENSE_VECTOR command. On an expression, KNN behaves differently:
- It performs an exact search that compares the query vector with the vector in every row. It doesn't build a vector index.
- It supports only the
similarity,similarity_function, andboostoptions. It ignores other options, such ask,min_candidates, andvisit_percentage. - The
similarity_functionoption sets the similarity metric. The accepted values arecosine,dot_product,l2_norm, andmax_inner_product. - If you don't set
similarity_function,KNNuses the similarity of the inference endpoint that produced thedense_vectorexpression or the query vector. If it can't infer one, it usescosine. - If the expression and the query vector come from inference endpoints with different similarities, the query
fails, even if you set
similarity_function. - If you set
similarity, it keeps only rows that are at least as similar to the query vector as the threshold. - If you request
METADATA _score, it adds a score to the relevance score of each row. Scores range from 0 to 1, except withmax_inner_productor aboostother than 1. - Rows whose vectors have a different number of dimensions from the query vector are filtered out with a warning.
- With
dot_product, every vector must be unit length. Rows whose vectors aren't unit length are filtered out with a warning. - To get the k nearest vectors, sort and limit the results explicitly, for example
SORT _score DESC | LIMIT 10.
To learn more, refer to runtime search.
Learn more about using ES|QL for search use cases.
| field | query | options | result |
|---|---|---|---|
| dense_vector | dense_vector | named parameters | boolean |
| text | dense_vector | named parameters | boolean |
k- (integer) The number of nearest neighbors to return from each shard. Elasticsearch collects k results from each shard, then merges them to find the global top results. This value must be less than or equal to num_candidates. This value is automatically set with any LIMIT applied to the function.
boost- (float) Floating point number used to decrease or increase the relevance scores of the query.Defaults to 1.0.
min_candidates- (integer) The minimum number of nearest neighbor candidates to consider per shard while doing knn search. KNN may use a higher number of candidates in case the query can't use a approximate results. Cannot exceed 10,000. Increasing min_candidates tends to improve the accuracy of the final results. Defaults to 1.5 * k (or LIMIT) used for the query.
visit_percentage- (float) The percentage of vectors to explore per shard while doing knn search with bbq_disk. Must be between 0 and 100. 0 will default to using num_candidates for calculating the percent visited. Increasing visit_percentage tends to improve the accuracy of the final results. If visit_percentage is set for bbq_disk, num_candidates is ignored. Defaults to ~1% per shard for every 1 million vectors
similarity- (double) The minimum similarity required for a document to be considered a match. The similarity value calculated relates to the raw similarity used, not the document score.
rescore_oversample- (double) Applies the specified oversampling for rescoring quantized vectors. See oversampling and rescoring quantized vectors for details.
similarity_functionElastic Cloud Serverless projects are autoscaled environments, fully managed by Elastic and available on Elastic Cloud. Availability Preview This functionality is in technical preview and is ready for evaluation. Use with caution in production; it is not recommended for mission-critical workloads. Elastic will work to fix any issues, but features in technical preview are not subject to the support SLA of official GA features. Specific Support terms apply. Serverless interfaces and procedures might differ from classic Elastic Stack deployments. The Elastic Stack includes Elastic's core products such as Elasticsearch, Kibana, Logstash, and Beats. Availability Planned We plan to add this functionality in a future Elastic Stack update. Subject to changes. Unless stated otherwise on the page, this functionality is available when your Elastic Stack is deployed on Elastic Cloud Hosted, Elastic Cloud Enterprise, Elastic Cloud on Kubernetes, and self-managed environments. This documentation corresponds to the latest patch available for each minor version. If you're not using the latest patch, check the release notes for changes.-
(keyword) The similarity metric to use when
KNNruns on adense_vectorexpression (rather than an indexed field). See the function description for more details about the default value. This option is rejected when used with an indexeddense_vectorfield, where the field's mapping determines the metric. Accepted values:cosine,dot_product,l2_norm,max_inner_product.
from colors metadata _score
| where knn(rgb_vector, [0, 120, 0])
| sort _score desc, color asc
| color:text | rgb_vector:dense_vector |
|---|---|
| green | [0.0, 128.0, 0.0] |
| black | [0.0, 0.0, 0.0] |
| olive | [128.0, 128.0, 0.0] |
| teal | [0.0, 128.0, 128.0] |
| lime | [0.0, 255.0, 0.0] |
| sienna | [160.0, 82.0, 45.0] |
| maroon | [128.0, 0.0, 0.0] |
| navy | [0.0, 0.0, 128.0] |
| gray | [128.0, 128.0, 128.0] |
| chartreuse | [127.0, 255.0, 0.0] |